LLaVA-Endo: a large language-and-vision assistant for gastrointestinal endoscopy
* 通讯作者 · † 共同一作
北京工商大学 · 计算机与人工智能学院
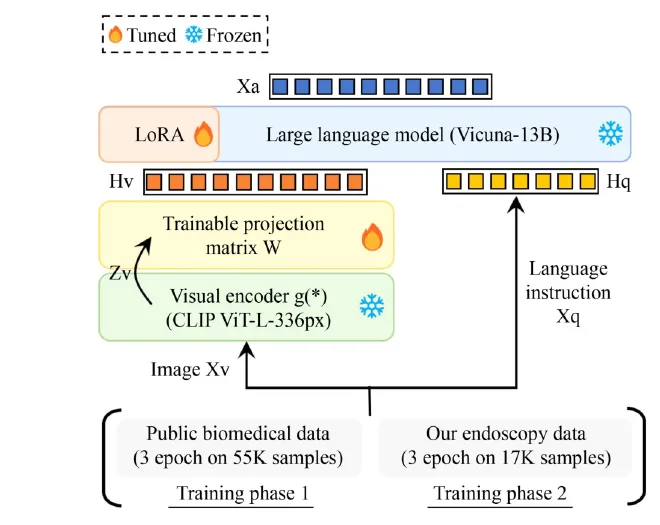
We introduce LLaVA-Endo, the first large language-and-vision assistant fine-tuned with gastrointestinal endoscopy knowledge, supported by a large-scale instruction-following dataset and progressive transfer learning from public biomedical data to domain-specific endoscopy data.
摘要
Existing AI-assisted gastrointestinal endoscopy systems typically rely on separate visual models for individual tasks, limiting interaction and adaptability to clinicians' instructions. LLaVA-Endo extends multimodal instruction tuning to gastrointestinal endoscopy by constructing large-scale image-text and conversational data from examination reports. Its progressive transfer learning strategy first adapts LLaVA with public biomedical data and then fine-tunes it with domain-specific endoscopy instruction data using LoRA. This two-stage design transfers general biomedical knowledge before specializing the model for endoscopic image understanding, enabling open-ended visual dialogue and clinically relevant reasoning across a range of gastrointestinal findings.
主要结果
The study assembled 3,423 endoscopy cases, producing 14,030 image-caption pairs, 17,504 instruction-following samples, and 64,640 dialogue samples. On a held-out set of 20 images, LLaVA-Endo achieved a GPT-4 evaluation score of 9.19 and an average human rating of 8.57, outperforming GPT-4V, Gemini, LLaVA-Med, LLaVA 1.5, mPLUG-Owl, and MiniGPT-v2. GPT-4 and human evaluation scores showed a correlation of 0.8073. Ablation results further support the benefit of the 13B model and the two-phase progressive transfer learning strategy.
BibTeX
@article{yao2025llavaendo,
  author  = {Yao, Jieru and Li, Xueran and Xie, Qiang and Han, Longfei and Jia, Yiwen and Liu, Nian and Zhang, Dingwen and Han, Junwei},
  title   = {{LLaVA-Endo}: a large language-and-vision assistant for gastrointestinal endoscopy},
  journal = {Frontiers of Computer Science},
  volume  = {19},
  number  = {4},
  pages   = {194331},
  year    = {2025},
  doi     = {10.1007/s11704-024-40319-8}
}